Turn PDF and Excel processes into a blueprint you review before coding. PALO Document Workbench runs local AI on your Mac, helps you inspect the data and workflow, and requires your review before export.
For business people who know the process, even if they do not write the code.
LOCAL INFERENCESOURCE-LINKED CANDIDATESHUMAN REVIEWEXPLICIT EXPORT
01 / The reason
The first governance decision happens before the prompt.
An Excel workbook. A process PDF. An idea for an app. The journey often starts by sending the whole business process to an AI coding tool.
PALO offers an earlier review step: analyse documents locally, inspect what the model inferred, resolve assumptions, and decide what may leave the workspace.
Use the route your organisation authorises. PALO does not override company policy or intercept uploads made directly to Claude Code, Codex, IBM Bob or other services.
Human Agency / Recruitment film
Your judgement. On the front line.
A short invitation to question what AI infers, review the evidence and help shape the PALO pilot.
3:59 / English narration and captions
Original illustrated recruitment film, with AI-generated English narration using the author’s voice profile through Gemini and MakeMyVoice, and an original score. This is not a recorded demonstration of the app.
No command line. No separate Python or Ollama installation. Open the Mac app and work through its local browser interface.
01
Prepare your private AI
The guided setup checks the Mac. With your consent, it downloads the model or verifies a compatible installed copy, then runs a test.
A ready local engine
02
Start with the example
Try the included fabricated process before using documents you are authorised to analyse. PDF and Excel sources stay in the selected local workflow.
A bounded document case
03
Check the model against the source
Inspect proposed entities, relationships, definitions and process rules. Use the ER graph, dictionary and source references to challenge assumptions.
Your reviewed interpretation
04
Review what leaves
Resolve individual candidates before exporting a development blueprint. Check the exported business logic before sharing it with any coding tool.
An explicit hand-off
A quotation is not proof that an inference is correct. Descriptions, identifiers and relationships can still be wrong. Human review is a required part of this pilot.
03 / Inside the app
A workspace. Not another setup project.
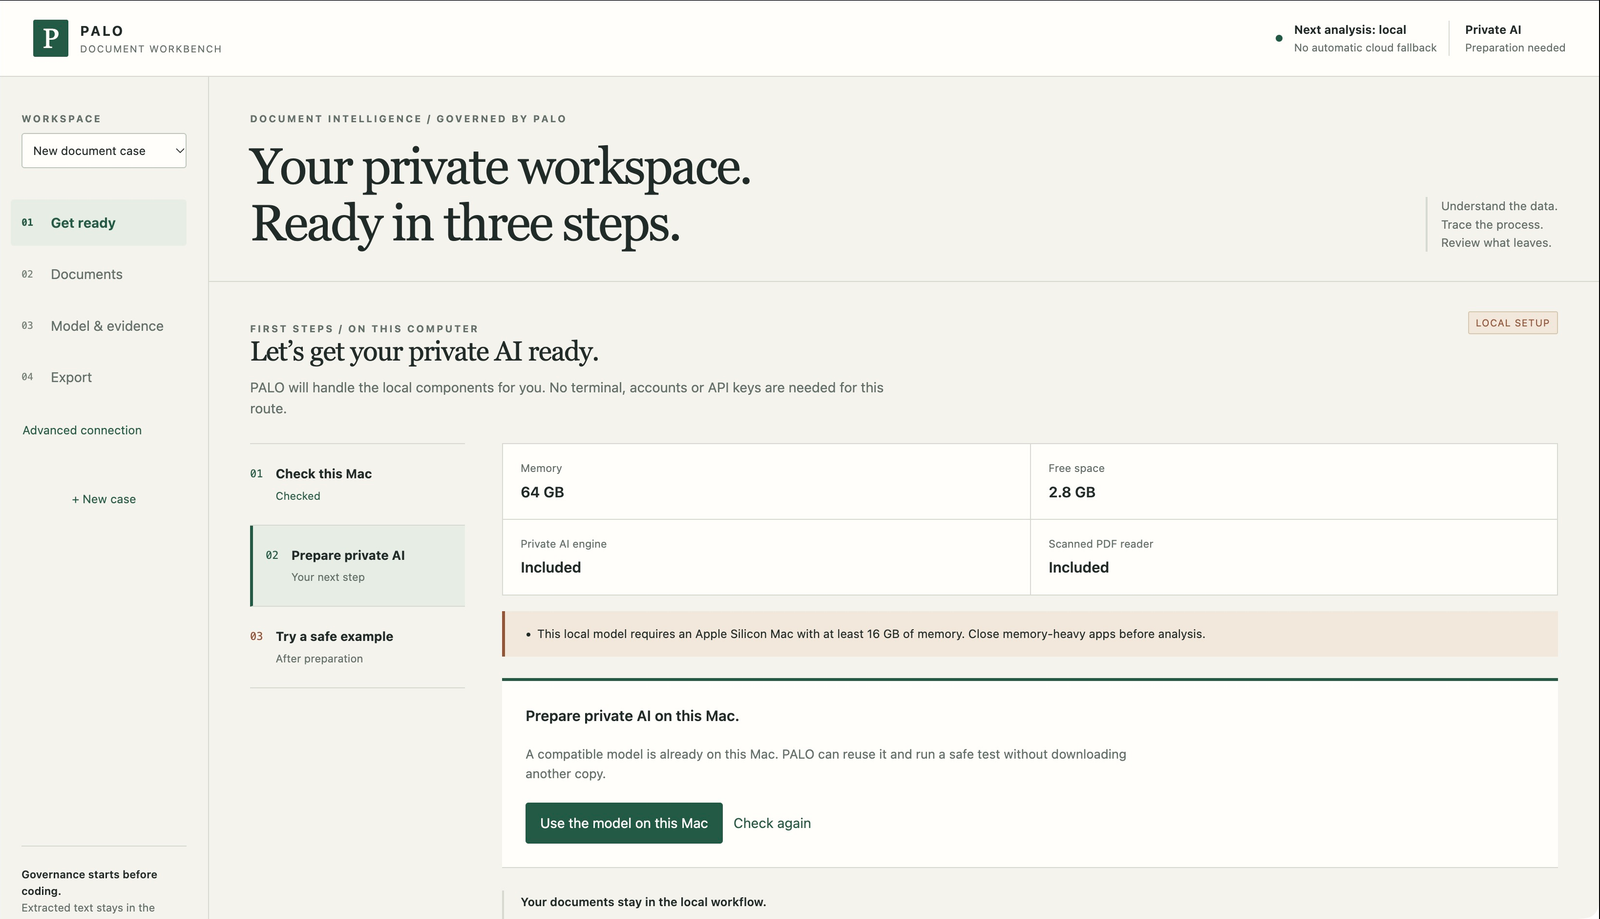
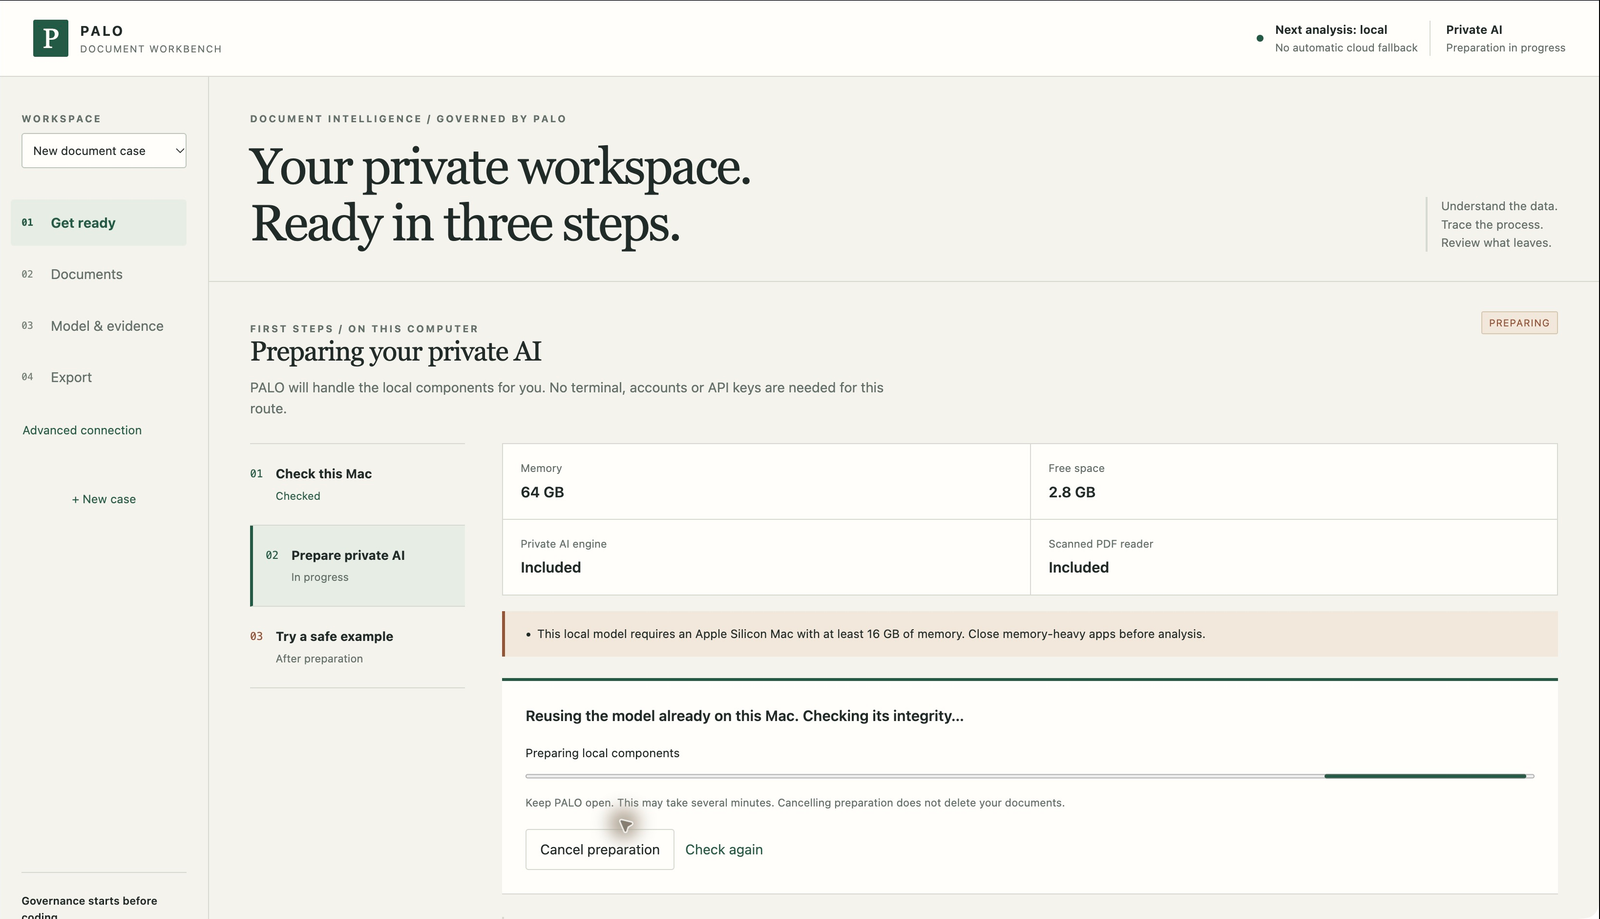
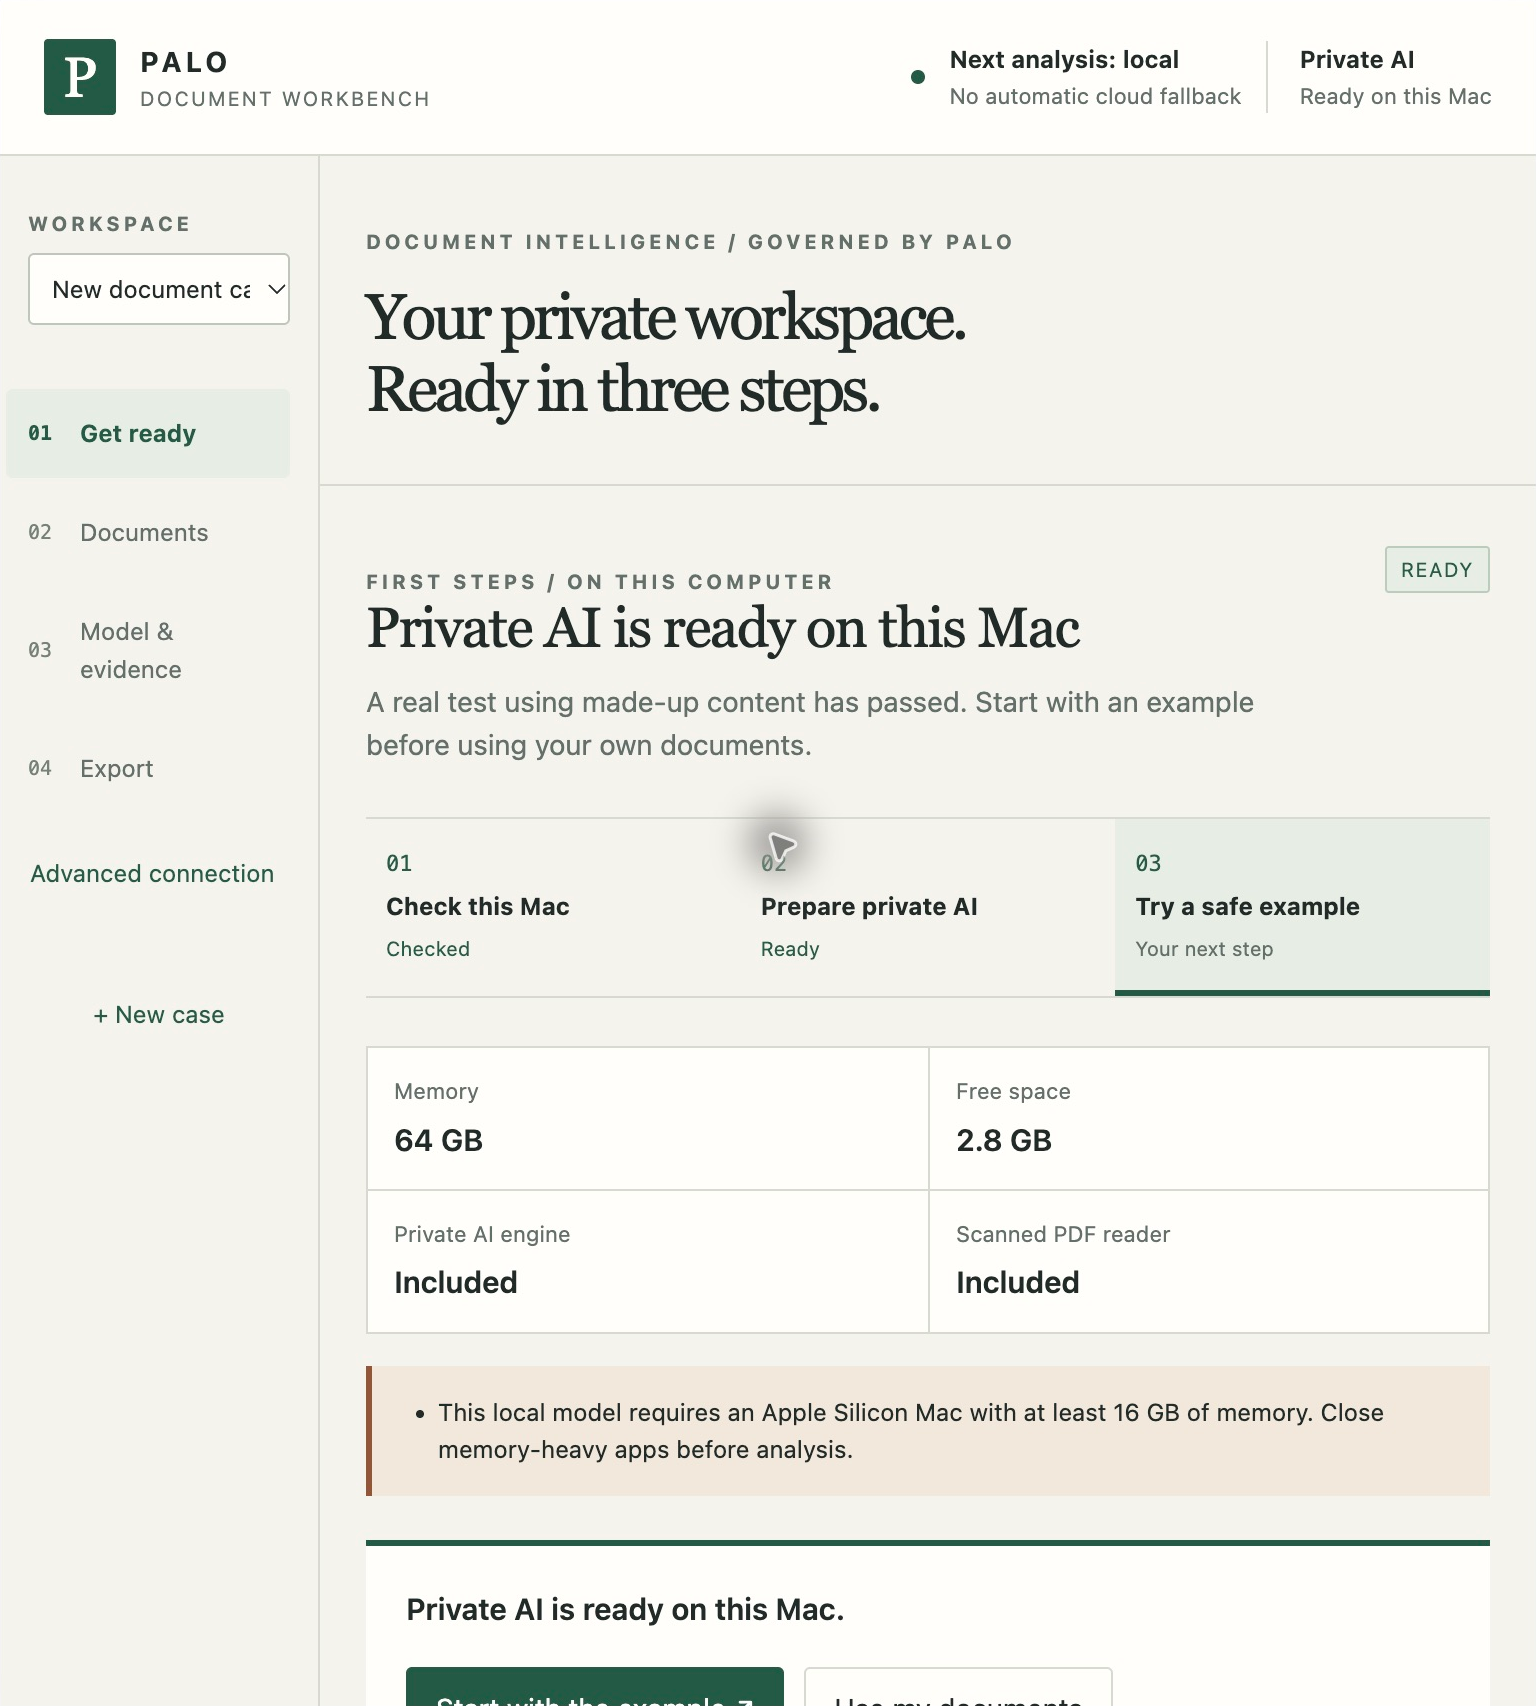
Actual English interface captures from the signed desktop preview. These show the existing-model reuse route on the qualification Mac.
01 / Get ready The engine and scanned-PDF reader are bundled. This Mac already had the compatible model; the capture does not demonstrate a first download.
02 / Prepare Preparation is visible. PALO verifies the model and tests local inference before marking the engine ready.03 / Ready A successful synthetic test unlocks the next step. This narrower browser view is still the Mac app, not a tablet release.
04 / Three PALO layers
Principles become reviewable steps.
The Workbench uses a pinned PALO reference snapshot, controlled dictionary and ontology. The business ER graph is an application projection.
01PALO Framework
Context and evidence
Connect the document case, lifecycle questions and review evidence. Keep sources and unresolved assumptions visible.
02PALO-AM
Bounded AI authority
The extractor proposes candidates within a defined task. It has no tools to execute the business process or deploy an app.
03PALO-AI-informed checks
Checks in the application
Model integrity, source references, graph constraints and export conditions are enforced by Workbench controls.
The separate PALO-AI production runtime is not integrated. This pilot does not issue canonical mandates, establish compliance or certify the correctness of a business model.
05 / Where inference runs
Local by choice. Explicit when connected.
YOUR MAC
A desktop app with a local web interface.
The native launcher starts the bundled backend and opens your browser on this Mac. After preparation, the installed model performs inference locally. There is no automatic cloud fallback.
Local processing does not protect against malicious software running as the same Mac user. Keep the device and its access controls secure.
YOUR ORGANISATION
An endpoint approved by your IT team.
An advanced connection can point to an explicitly configured company inference endpoint. Your IT team must approve the provider, data handling and network route.
This option is not a managed enterprise deployment, tenant isolation, SSO or an automatic integration with coding tools.
Engineering update / measured 9 November 2026
The pipeline finishes. The quality gate stays open.
Three original public PDF repositories, each larger than 100 MB, completed import, local inference and reviewed blueprint export. This is execution evidence for a local 0.3.2 candidate, not qualification for unassisted business use.
Completed cases
3 / 3
Repository sizes
107–163 MB
Targeted tests passed
91
Business release
Not qualified
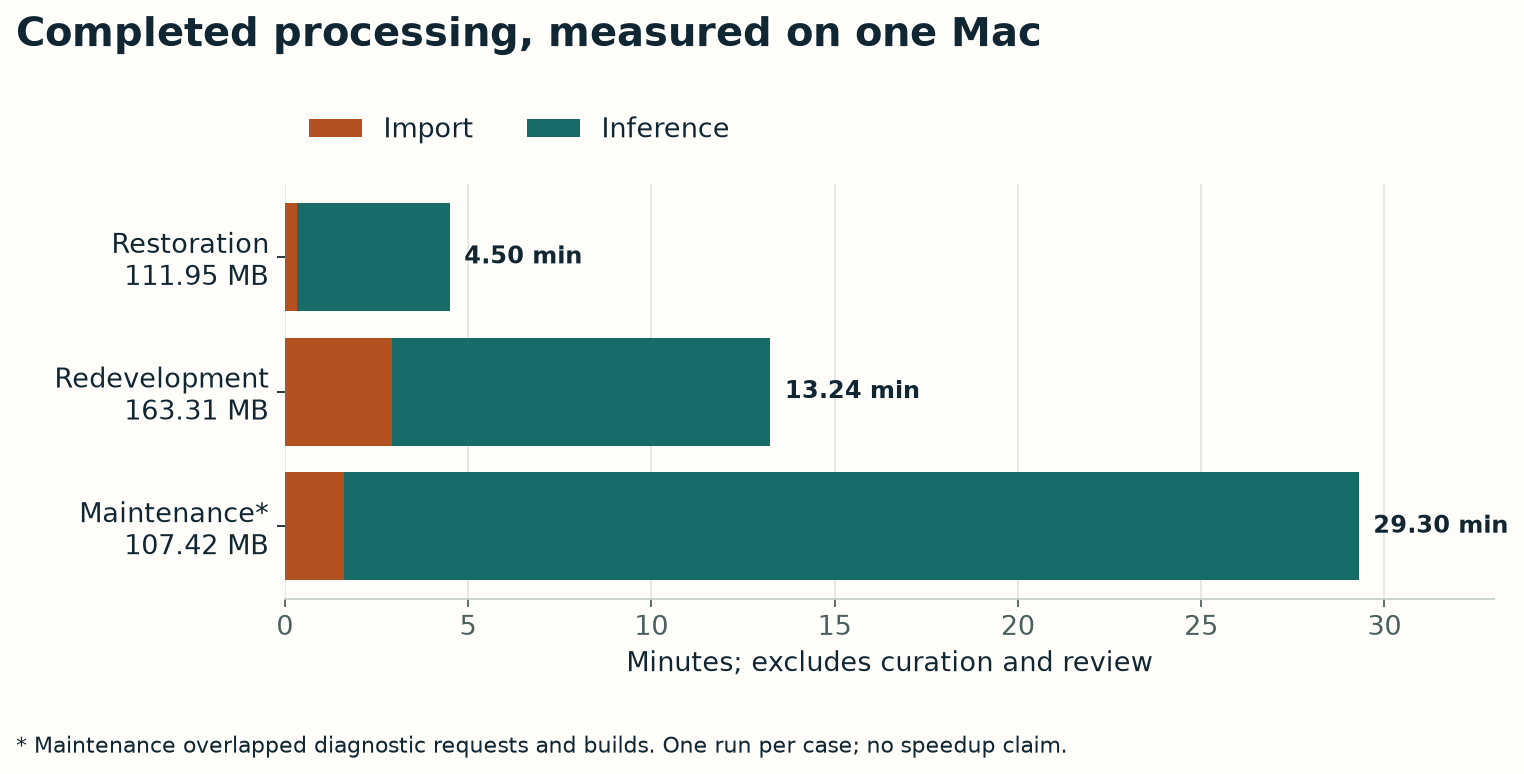
Observed processing time
One run per repository on an Apple M3 Max with 64 GB RAM and macOS 27.2. The model was Liquid LFM3-1.7B Q4_K_M. Import and inference exclude source inspection, curation and export review.
Bars share a zero baseline and show import plus inference. Maintenance overlapped nine diagnostic requests and package builds. These are shared-machine observations, not a controlled speedup benchmark. Download chart PNG.
Completed runs; MB = 1,000,000 bytes
Public repository
Original size
Import
Inference
Batches
Export
University Lakes restoration
111.95 MB
20.151 s
249.585 s
24 / 24
11 curated candidates
Dayton Mall redevelopment
163.31 MB
175.288 s
619.398 s
64 / 64
20 curated candidates
FAA maintenance handbooks
107.42 MB
97.301 s
1,660.470 s
189 / 189
10 curated candidates
Unique, unmodified files with recorded hashes. No padding or duplicated PDFs. All 277 batches completed with zero recovery requests. Recovery and resume behaviour were tested separately. These PDF runs do not qualify large Excel workbooks or complete diagram interpretation.
Before
Import and inference stopped.
The preserved 0.3.0 source/API baseline completed 0 of 3 imports. The subsequent corrected-import pipeline failed all 6 analyses across two runtime arms. No blueprint was exported.
The baseline includes two modules recovered from matching cached bytecode. It is not a fresh test of the released binary.
After
3 of 3 reviewed exports.
Bounded extraction, checkpoint validation and explicit review now complete the three cases. Unreviewed and stale-preview exports remain blocked. The packaged backend also exported all three reviewed copies.
Prompts, batching and schema changed. Failure durations cannot establish throughput or a speedup caused by the runtime fork.
Why completion is not enough
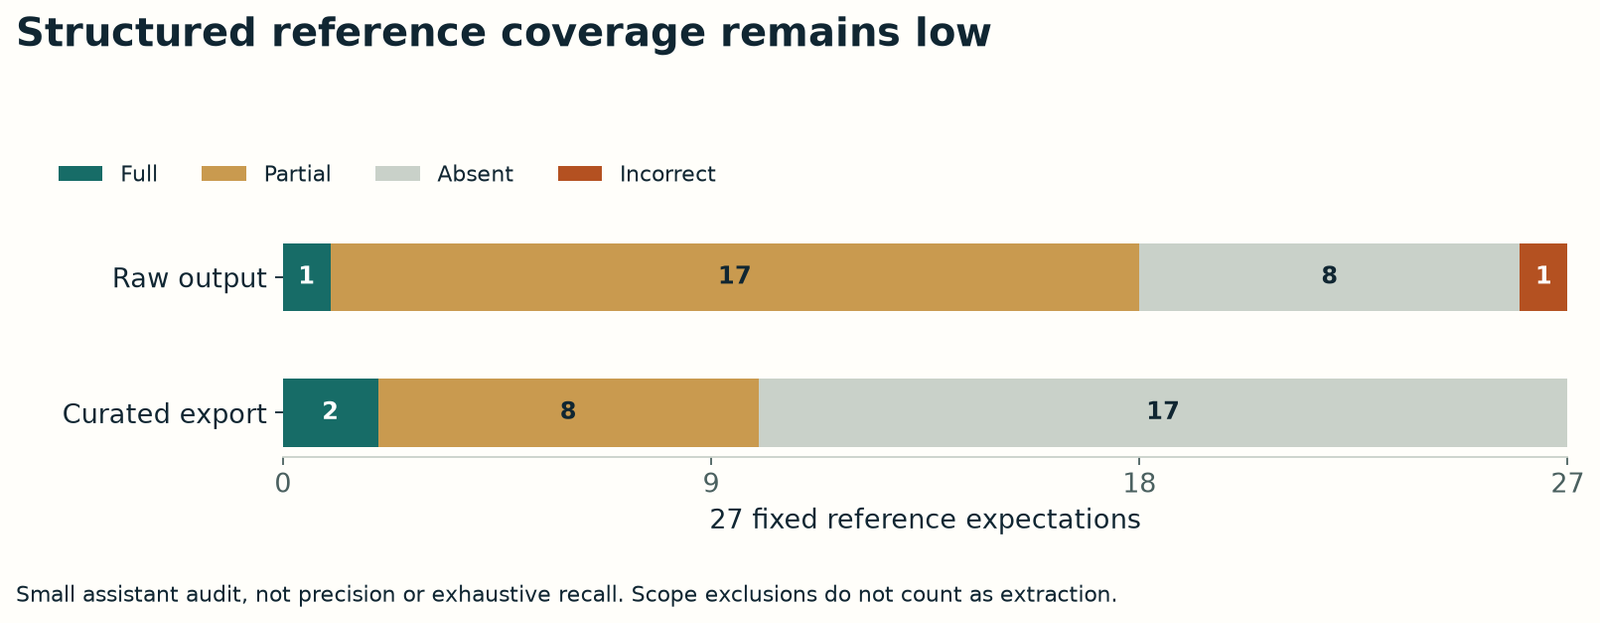
Passing a citation or structure check is not proof of semantic accuracy. Curated exports required assistant corrections and exclusions. Excluded candidates may be wrong, duplicated or outside the selected scope. Download chart PNG.A small assistant audit against expectations fixed before inference. Full representation requires the expected kind, source support, correct bindings and qualifiers. This is bounded coverage, not precision or exhaustive recall. Scope exclusions do not count as successful extraction. Download chart PNG.
Not ready for an unassisted business rollout.
The model still confuses neighbouring concepts, misbinds descriptions and omits requirements. Only 41 of 1,095 raw candidates were retained in scoped drafts, with 14 structural corrections. The candidate cap was reached in 275 of 277 batches. All prepared text entered inference; that does not mean every requirement was extracted.
The exports are selected catalogues and glossary material, not complete ER models or deployment specifications. All review decisions are labelled automated assistant audit, not human or domain approval. Two parcel maps remain uninterpreted and were explicitly excluded from the nonspatial scope.
Corrections now in the candidate
128 MiB per file, 250 MiB per repository and 2,000 pages per PDF, with additional text and worksheet budgets.
Exact source fragment IDs; bounded recovery of truncated responses and validated checkpoint resume.
Editable candidate type, name and bindings, with evidence preserved and dependent decisions reopened when needed.
Fresh-preview export checks, explicit assistant identity and a graph that excludes discarded candidates.
Review and distribution status
GLM-5.3 Effort Max supplied the initial web review. Gemini 4 Argon Medium supplied code reviews; High was not available in the inspected selector. Neither independently ran the benchmark. The final GLM follow-up was service-limited; the final Gemini response was only partly captured.
The local 0.3.2 build 6 is signed and its frozen backend was tested. It has not been newly notarised or published as an installer. The public 0.2.0 preview does not contain these repairs. Clean-machine and minimum-hardware qualification remain open.
Inspect and reuse the evidence
Published 10 November 2026. Final review/UI fixes postdate the frozen inference runs; source hashes and runtime identity are included in the measurements. Raw private workspaces and reviewer interface captures are not part of this public bundle.
Historical 0.2.0 preview evidence, retained for traceability. These results do not describe the 0.3.2 engineering candidate or validate its semantic quality.
✓ Observed
The earlier 0.2.0 application and installer were signed, notarised by Apple and ticket-stapled. Gatekeeper accepted both. This status does not transfer to 0.3.2.
Real local inference on a fabricated PDF and Excel workflow produced 15 candidates.
Local inference and OCR completed with external network access denied in a test harness, after model installation.
A full 4.7 GB download into an empty model directory passed after explicit cancellation at 5% and retry, including hash verification and a real inference probe.
All 39 Python tests passed. Export was blocked until candidate review; restart and owned-process cleanup checks passed.
○ Still to qualify
A clean second Mac and recovery from an unexpected network drop. The successful cancellation/retry test used the existing qualification Mac.
The configured minimum of macOS 26 and 16 GB RAM. Execution so far was on macOS 27.2 with 64 GB.
Usability with nontechnical pilot participants and more varied document sets.
Accuracy, completeness and practical benefit across real business workflows.
The test also exposed an error. Two generated descriptions asserted uniqueness that the source did not establish. Review removed those claims before export. Exact source references alone did not make the interpretation correct.
PALO Document Workbench 0.2.0 / earlier public preview
This download does not include the 0.3.2 pipeline repairs above. For the supervised earlier preview, download the disk image, drag PALO Workbench to Applications, open it and follow Get ready. Start with the included example.
Controlled pilot, not a general production release. The first full download and explicit cancellation/retry passed on the existing test Mac. Clean-machine installation, minimum hardware and unexpected network-loss recovery remain unqualified. Join the supervised pilot before relying on it for business documents.
We are inviting business users, IT teams and governance practitioners to a controlled pilot. Start with synthetic documents. Challenge the extraction, review and export workflow.
This opens an email to info@paloframework.org. Share your Mac specification and what you want to test. Do not attach company documents, personal data or secrets.
Field notes
Before you enlist.
Is this a web app or an installed app?
It is an installed Mac app. Its native launcher starts a local service and opens the interface in your browser. This is not a hosted document-upload website.
Will it write or deploy my application?
No. This pilot prepares a reviewed development blueprint. Your coding tool and IT delivery process remain responsible for implementation, testing and deployment.
Can I send the exported blueprint to any AI service?
Only if you are authorised to do so. The blueprint can still contain confidential business logic. It is not an anonymisation guarantee or permission to bypass company policy.
Does Apple notarisation mean the AI output is approved?
No. Notarisation concerns distribution of the software. It does not validate document interpretations, business correctness or compliance.
How should I report a problem?
Describe the step, the expected result and the observed result using a fabricated example. Include the app version and Mac specification. Do not send originals, private logs or sensitive screenshots.